Claude Sonnet 5.5 is an AI model from Anthropic launched on September 28, 2026, the second model in the Claude 5.5 family after Opus 5.5. The API price is 2 USD per million input tokens and 10 USD per million output tokens, exactly half that of Opus 5.5, while running 30% faster than Sonnet 5 and costing up to 30% less per task. According to Anthropic, Sonnet 5.5 is strongest at having clear everyday scope, fixing bugs, and creating documents, slides, and polished spreadsheets; while complex work, open-ended tasks requiring long-term judgment still belong to Opus 5.5.
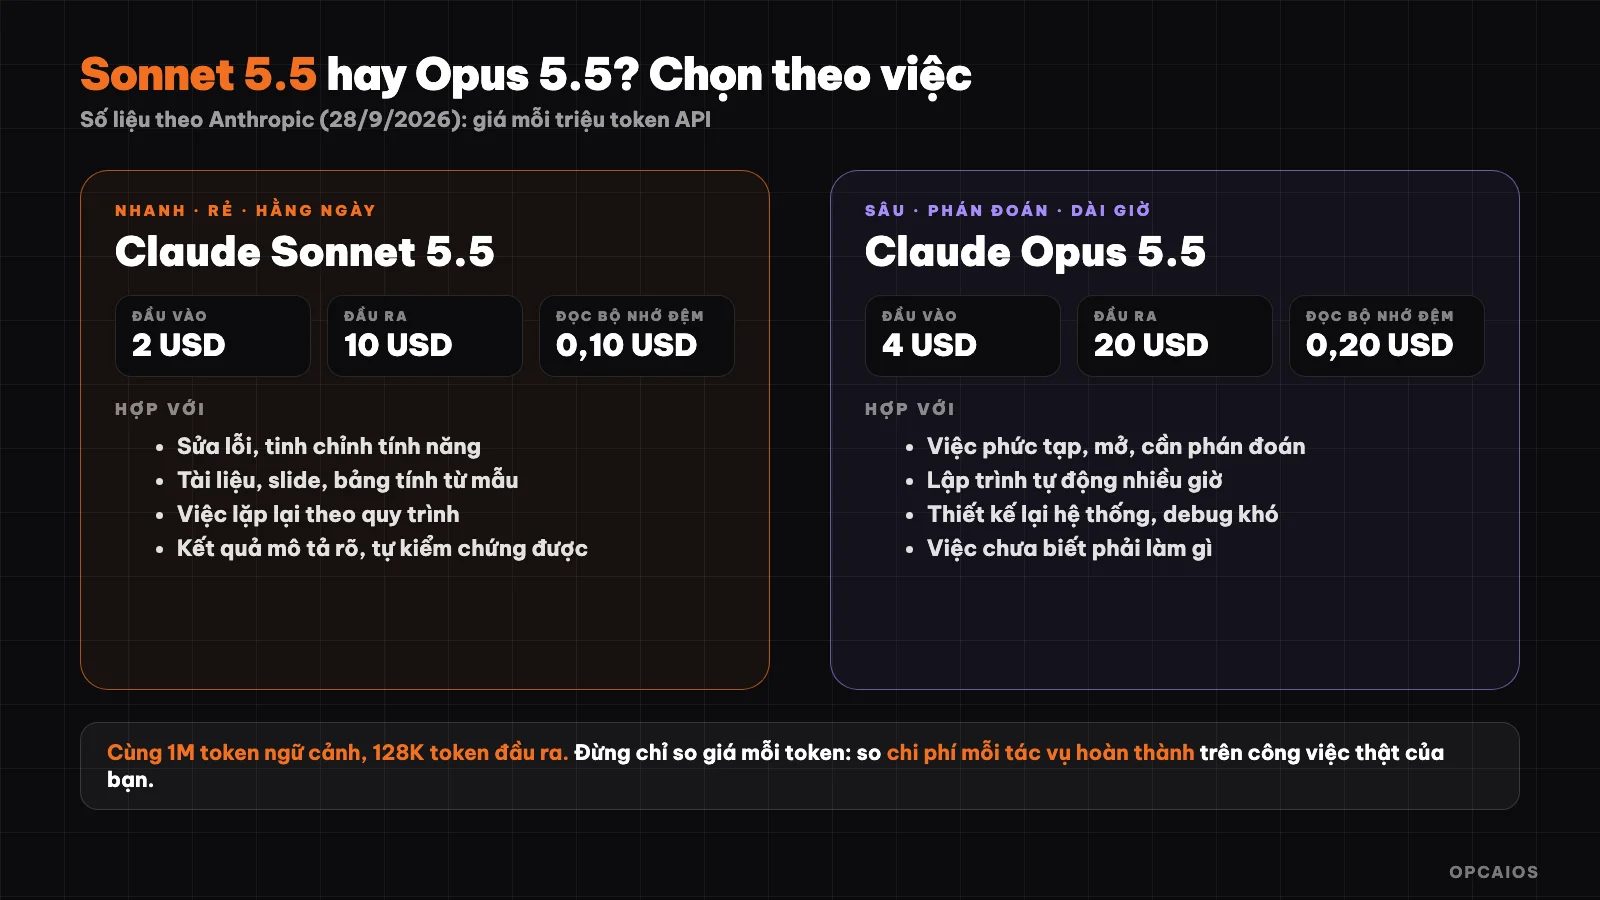
Sonnet 5.5 and Opus 5.5 side by side: API price, strengths, and how to choose. Data from Anthropic. Diagram: OPCAIOS.
What's new in Claude Sonnet 5.5?
Sonnet 5.5 is a clear upgrade from Sonnet 5 in four ways, according to Anthropic's official announcement:
- Performance: Terminal-Bench 4.0 score (a test for command-line agent code writing) increased from 10.3% to 70.6%. On GDPval-AA, a test of real work across 44 professions, the score is nearly equal to Opus 5.5.
- Collaboration: clearer writing style than the previous generation; early testers describe it as a better discussion partner than Sonnet 5.
- Cost: price stays the same as Sonnet 5 but requires far fewer tokens for the same task; cache read price drops from 0.20 to 0.10 USD per million tokens.
- Speed: output generation 30% faster than Sonnet 5, the fastest Sonnet to date.
This is also the first Sonnet model launched with cybersecurity safety measures; see more in the final section of this post. Haiku 5.5 for high volume, cost-sensitive work launches a few weeks later.
Sonnet 5.5 benchmarks compared to Opus 5.5 and Sonnet 5
Benchmarks show Sonnet 5.5 approaching Opus 5.5 on many tests, but not replacing it in every task. Data below comes from Anthropic's table, published by the maker:
| Benchmark | Sonnet 5.5 | Sonnet 5 | Opus 5.5 |
|---|---|---|---|
| Terminal-Bench 4.0 (agent code writing) | 70.6% | 10.3% | 66.4% |
| CursorBench 4.0 (real programming work) | 55.5% | 34.1% | 57.8% |
| GDPval-AA (work across 44 professions, Elo score) | 1,844 | 1,449 | 1,846 |
| OSWorld 2.1 (computer control) | 80.1% | 57.0% | 81.8% |
| Humanity's Last Exam (with tools) | 64.5% | 54.9% | 67.7% |
| Chartography (chart reading) | 61.6% | 15.6% | 64.4% |
Two points to note. First, Terminal-Bench shows Sonnet 5.5 higher than Opus 5.5, but a single benchmark score does not mean the two models are equal. Second, Anthropic itself states that according to their own tests and outside tests, Opus 5.5 remains clearly stronger on complex, open-ended work requiring continuous judgment. Scores are just one angle; try it on your own work, as guided in the post Which AI model should I choose?.
What is the price of Claude Sonnet 5.5 compared to Opus 5.5?
The API price of Sonnet 5.5 is exactly half that of Opus 5.5 for both input and output. Pricing per million tokens (from Anthropic's pricing page, checked October 22, 2026):
| Type | Sonnet 5.5 | Opus 5.5 |
|---|---|---|
| Input tokens | 2 USD | 4 USD |
| Output tokens | 10 USD | 20 USD |
| Cache read | 0.10 USD | 0.20 USD |
| Cache write (5 min) | 2.50 USD | 5 USD |
| Batch processing (input / output) | 1 USD / 5 USD | 2 USD / 10 USD |
Example calculation (illustrative numbers, ignoring cache): a task using 100,000 input tokens and 20,000 output tokens costs about 0.40 USD with Sonnet 5.5 (0.10 million × 2 + 0.02 million × 10) and about 0.80 USD with Opus 5.5 if both models use the same number of tokens. In reality each model uses different token counts, so comparison should be based on cost per completed task, not just price per token.
Other specs from the official model page: 1 million token context window, 128,000 token max output, training data reliable through June 2026, model code claude-sonnet-5-5. The model is available on Claude Platform, Amazon Bedrock, Google Cloud, and Microsoft Foundry.
When to choose Sonnet 5.5, when to choose Opus 5.5?
Choose Sonnet 5.5 for work with clear scope and self-verifiable results; choose Opus 5.5 for ambiguous work, requiring deep judgment and long-running automation. Based on Anthropic's description:
Good fit for Sonnet 5.5:
- Daily programming with clear scope: bug fixes, feature refinement.
- Large development volume, needs speed and low cost.
- Creating documents, slides, spreadsheets from existing templates.
- Repetitive work following fixed procedures.
Good fit for Opus 5.5:
- Complex work requiring careful judgment.
- Long-running automated programming.
- Redesigning large systems, difficult debugging.
One point to balance: Anthropic's model page recommends starting with Opus 5.5 for most workloads if you're unsure, and only upgrading to a higher model when your evaluation falls short. A practical way to decide: start with Sonnet 5.5 for work where you can describe the end result and self-check; assign Opus 5.5 to work where you don't yet know what to do. The post from @claudecode84 also notes that in some work like spreadsheets and investor documents, testing showed Opus 5.5 completing faster and cheaper with equivalent quality, so real measurement is needed.
What is effort level and which should you choose?
Effort is a setting that controls how deeply the AI thinks and works: low level answers quickly and uses fewer tokens, high level reasons longer and checks more thoroughly. According to Anthropic, in the Claude app and Claude Code the default is Medium, while on Claude Platform (API) the default is High.
Anthropic reported that on some benchmarks, Sonnet 5.5 at Low or Medium exceeded Sonnet 5's top score at about one-tenth the cost per task. Practical guidance (from @claudecode84's synthesis of official documentation): chat needing speed uses Low or Medium; programming with clear instructions uses Medium; hard or long work uses High; higher levels for very long automated tasks; Max level shouldn't be used regularly. The post also cites third-party results showing that at Max, Sonnet 5.5 uses very many tokens and may cost about 50% more than Sonnet 5 at Max; OPCAIOS hasn't verified this result, but it shows why you shouldn't set higher than necessary.
How to use Sonnet 5.5 in Claude Code
In Claude Code, you choose the model yourself using the /model command or startup flag. According to @claudecode84's post, two common ways:
/model sonnet
claude --model claude-sonnet-5-5
The same post describes the /model opusplan mode: planning stage uses Opus 5.5, coding stage uses Sonnet 5.5, which is "design with Opus, execute with Sonnet" with just one setting. Modes and command names may change between versions, so check the current Claude Code documentation. Also measure in practice: setting Opus to plan then handing to Sonnet to execute isn't always cheaper than using Opus alone.
A few habits reported by users (not manufacturer commitments): request clearly "run tests, check types and build then show results" instead of trusting a "done" claim; at low effort level the model may stop partway to ask, so specify when stopping is allowed. On the matter of AI writing code for wrong library versions, see the post AI writes code for wrong version.
How to write requests for Sonnet 5.5 to be stable?
A good request has four parts: what needs doing, necessary information, what not to do, and what counts as done. This approach is more stable than listing dozens of detailed steps, because describing the goal and completion conditions then letting AI choose how.
Some specific tips from @claudecode84's post:
- When you just need ideas: add "give options then stop, don't create files", because broad requests sometimes make AI build whole presentations.
- When asking information or changes like prices or terms: request checking by search before answering.
- When making slides: provide your company template first so AI follows layout, typeface, colors.
- When making spreadsheets: request "use formulas", then change some inputs to see results update automatically.
- When switching models midway: open a new conversation, because switching partway loses the context already reasoned and the cache has to rebuild.
Safety Notes and Limits of Sonnet 5.5
Sonnet 5.5 has two things you should know before using it. On safety, because the model's cybersecurity capabilities have grown significantly, Anthropic is rolling it out with measures similar to Opus 5.5: users can still find and fix bugs in code normally, but high-risk cybersecurity tasks will explicitly switch to answering with Sonnet 5, with a notice when switching. For biology, the measures are the same as Sonnet 5; some legitimate microbiology or virology requests may be flagged by mistake.
On limits, according to Anthropic itself, Opus 5.5 is still stronger on open and complex work. The post by @claudecode84 includes some third-party remarks, unverified: Sonnet 5.5 may fall behind Opus 5.5 on knowledge tests (54% versus 66%), sometimes fills in expected values in memory-based testing on its own, or may be rough on design details. Common ways to reduce risk: have a machine verify results and keep a human reviewer at the final step.
Frequently Asked Questions
When did Claude Sonnet 5.5 launch and how much does it cost?
Sonnet 5.5 launched on 28/9/2026. API pricing is 2 USD per million input tokens and 10 USD per million output tokens, exactly the same as Sonnet 5 and half that of Opus 5.5.
Is Sonnet 5.5 as good as Opus 5.5?
Nearly level on many tests like writing agent code and work across 44 jobs, but Anthropic says Opus 5.5 is still clearly stronger on complex, open, long-judgment work. Try it on your actual work.
Should I use Sonnet 5.5 or Opus 5.5 for programming?
Use Sonnet 5.5 for daily programming with clear scope like bug fixes and feature tuning; use Opus 5.5 for work that stretches hours of automation, system redesign, or tough debugging. You can combine them: Opus plans, Sonnet executes.
Can I use Sonnet 5.5 for free?
According to Anthropic, anyone can chat with Sonnet 5.5 on Claude.ai (web, iOS, Android). Usage limits for each plan may change; see Anthropic's plans page. Using through API is billed by token.
What is the model code for Sonnet 5.5 in the API?
The code is claude-sonnet-5-5 on Claude API; on Amazon Bedrock it is anthropic.claude-sonnet-5-5; on Google Cloud and Microsoft Foundry it is claude-sonnet-5-5. To connect your systems through API, see the post What is API? and information on Claude.
Source: Claude Sonnet 5.5 announcement (28/9/2026), Anthropic's models and pricing pages (checked 22/10/2026); usage tips from the post by @claudecode84 on X (30/9/2026), third-party remarks not verified by OPCAIOS. Pricing and limits may change.
Translated from Vietnamese with AI. Read the original.
Want to apply this in your business?
Book a free 30-minute call (Vietnam time, in English or Vietnamese).